
Every dot in these graphs is composed of multiple benchmarks smooshed together.
Benchmarks are by definition a curated set of things that can be measured and evaluated.
Things that can be measured and evaluated can be (expensively) trained on.
The progress we are observing comes from figuring out how to measure and evaluate particular aspects of intelligence, and then expensively training on feedback loops made of those exact measurements, and synthesized data representing further measurements (literally benchmaxing).
What is not shown in these graphs are the set of things that intelligence can do, which are difficult, expensive or impossible to measure and evaluate.
That set of things is much larger than the set of benchmarks represented in the graph.
Therefore the post is misleading in the sense that the "superintelligence" being targeted is "jagged" to use Karpathy's term, and we infact already have jagged superintelligence (calculators, compilers, Bayesian spam classifiers, etc.)
We are witnessing a profound explosion of much more jagged superintelligence, restricted to the exact domains that can be (expensively) RL'ed on.
This isn't really comforting to me for 2 reasons:
1. A key insight of foundation models is that capabilities are correlated. For example, training on code improved general reasoning capabilities: https://arxiv.org/abs/2309.16298
2. A profound capabilities explosion in easily measured domains will still feel very different to today. Like, the moment we come up with a systematic, objective way to verify a task, we become obsolete at it?
But picture the next 10 years, where all kinds of people, organizations, etc train in a ll different ways with diff philosophies and goals - I feel like there will be some good, unusual, interesting ones in there, even if they all have their own complex set of limitations.
Apart from physical world interactions which is obviously lacking, which domains lag behind and do not improve then?
AI is accelerating my work...work which only exists because of AI.
If I had to do my individual tasks without AI, I would be slower. But if I take a step back, I'm really not changing the world any faster than I was before.
I think where LLMs truly shine is personal greenfield projects, maybe start a side project
Completely agree. LLMs are amazing for side projects.
The other place they are amazing is in working with legacy code bases. I mean, the kind the dev team always wants to throw away. First, even if you do want to throw it away, you can first find out what it does and realize it does more than you think it does. You can also create integrations to more modern components which can be used to extend it. You can also create a pretty decent test suite if you do not have one. And, once the behaviour has good test coverage, you can re-write it into something more modern. You can even completely change the architecture while ensuring compatible external behaviour. Remember, this is all in place of “throw it away and start over from scratch, only to discover that the scope is much larger than expected”.
You could already do all of that. Like, none of that is infeasible to achieve on a scale of weeks in most cases.
It’ll still take weeks with AI in the picture, but for some reason management is more willing to plan it when they also have the additional token bills to pay.
It was often not organizationally feasible because you needed permission to spend those weeks up front, instead of working on something else, just to get to where you knew enough to give approval to finish the work.
Now, you can make enough progress with one developer’s quiet afternoon to be confident and finishing the work also takes less time.
The technical grasp of the legacy codebase was a factor, but often not the largest.
There's this joke like "I used to have 5 unfinished side projects, but AI changed everything. Now I have 30 unfinished side projects". And in my case it's not even a joke
Can't really blame AI for that though.
They aren't blaming AI, they are just backing up the "not much has changed" idea.
It's always been easier to start a project than finish it, and LLMs make starting a project roughly free. I'm not sure they change how much work it is to finish it all that much.
I mean, I have finished more side projects than before. So they do change it. Just not as dramatically.
Of course you can. LLMs take you from 0 to 80 instantly. They are then completely incapable of getting from 80 to 100 and making something worth shipping to production. They are the ultimate unfinished side project generator.
Have you, uh, used them recently? LLMs absolutely get to 100 now.
For a definition of 100 which includes nobody actually using any LLM-written software in production at scale, other than Codex and Claude Code, which are both horrifically buggy, bloated, insecure pieces of software that are only used for their association with another piece of software gated behind them and which nobody would choose to use if they were themselves third-party harnesses. If LLMs could get to 100, the promised software revolution I am told is here every day would actually be visible.
We would be using LLM-generated compilers, an LLM-generated OS, an LLM-generated browser, LLM-generated databases, etc. etc. etc. etc, and not only are we not using all of those things, we're not using a single one of those things. Nobody is buying LLM-generated games, nobody is using LLM-generated consumer applications that replace Photoshop or Final Cut or Blender or Unity ("ArtCraft" is itself an admitted scam from its own prompter, who even admitted here that he lied about its capabilities on Reddit to build hype), nobody is accomplishing anything of economic value. LLMs are obviously hundreds of times more "productive" than humans, so the moment they can reach 100, all of these things would happen basically overnight, and yet none of them have happened. Curious, isn't it?
What prevents AI from cloning photoshop feature for feature, bug for bug?
You have the perfect verifier.
So relatable. But I have some finished projects now and some of them I use daily.
No idea what you're talking about. I'm using AI to help me on my paperclip production side project, and it's going great!
Skill issue. I had 30 unfinished side projects even before AI. Just raw talent.
Yeah, when there is no code review requirements and no pesky production database you can't just yolo :)
At work, they mostly let me increase quality, because it's easy to say find all parsers in my code base and fuzz them.
It is great. I just had claude yolo a human in the loop image segmentation pipeline last night. It cut weeks of work down to an evening like 4h. Segment Anything 3.1 + Napari final touch.
I'd also say: when you really understand a domain well and you're a one-(wo)man show, you can just fly!
Of course, you can make a giant pile of doggy-doo-doo, but that was always true, just you can now make an epic Giza-sized pile.
> work which only exists because of AI
Could you elaborate? What work are you doing which only exists because of AI?
For all my user facing work I’m now required to do an AI summary of what I did and the impact. That summary is then graded by AI, against an AI generated rubric. For my yearly review, I use AI to summarize my summaries, and my managers AI summarizes the AI generated grades.
I’m also required to explain how I use AI in my work. I must plan all of my future work, with an AI tool. Another AI assesses whether my work is aligning with planned work.
Before I work and after I work, there is a million circular references that exist solely because of AI. These have scaled because it’s so easy to do with AI, but the we’re wasting so much time doing a ton of extra things very efficiently.
Let me do my job. My manager should know how I’m doing. Maybe highlight key wins. CSATs/etc go out every year.
Even before my last job had internally approved AI, my manager told me how he was using chatgpt on his personal computer to prepare our yearly reviews. Then when they released AI internally a few weeks later, it was still review time, and their first advertised use case was for doing your own self eval and the evals for your reports. I am willing to deal with vibed code but turning over employee evals to AI too is a sign of truly terrible management
Does any of this get read? I mean by an actual human?
This sounds truly Kafkaesque. And thank you for finally allowing me to use that word in earnest.
I honestly got turned off a few sentences in. Sounds like a nightmare.
> This sounds truly Kafkaesque. And thank you for finally allowing me to use that word in earnest.
Kafka and Byzantium had a baby.
So….you have outsourced multiple layers of middle-management to AI? I am not sure getting AI to write and review your TPS reports is going to move the needle.
The TPS production/consumption stats disagree, they're up 300% just this quarter. Can't argue with results
Its true, a part of me died when an "AI first" company after adoption of AI introduced a mandatory design report (waterfall all over again) for EACH jira ticket before starting to code
Imagine developers move faster because of AI programming! No lets create more slop for other slopmachines
You aren’t changing the world at all.
Then no one is by that logic.
The bureaucracy is expanding to meet the needs of the expanding bureaucracy. -Oscar Wilde
I mean, for many years I worked on software applications for provisioning and controlling cloud orchestration platforms that only existed... to serve software applications.
It's not that deep—there were many more verticals outside of control plans, and there are now many more verticals outside of machine learning.
Or am I missing the point?
Not trying to discredit the premise but I do wonder how much this is from vertical scaling of model intelligence in weights vs the sheer amount of capital being thrown at training and horizontal scaling of agent swarms etc.
Anecdotally it seems like the majority of continued uplift comes from models doing more and exploring more of the search space, and we are getting better at giving them embarrassingly parallel problems to Hoover up with infinite token spend.
Counterarguments to that premise:
1. Intelligence per dollar spent/token output seems to be increasing rapidly. Opus 4 was $15/75 per million input/output tokens when released. Opus 5.5, which is significantly better, is $4/15. Sure it cost more money upfront to train Opus 5.5, or the bigger model (Fable 5.5) which tuned it, but once it is reached, there are massive diffusive effects.
2. The capital equation is still favoring more spend. Anthropic's revenue is growing rapidly and they are profitable on inference. Huge upfront spend for realized gains later on is standard for R&D. As long as serving the models is profitable and generates more value than the energy/compute consumed
3. The search space is too large to assume that improvement in AI assisted research is just models dumbly trying every combination until something works. For every additional bit searched, the space doubles, so even a trivially small combinatorial exploration incurs prohibitively large costs. Intelligent searching which continuously prunes that space along dimensions of effectiveness is not a trivial skill and is among the emergent accoutrements of these smarter models.
> 2. The capital equation is still favoring more spend. Anthropic's revenue is growing rapidly and they are profitable on inference. Huge upfront spend for realized gains later on is standard for R&D. As long as serving the models is profitable and generates more value than the energy/compute consumed
But they are essentially fighting for smaller and smaller part of the pie. The better open models are the less you need frontier models, so the frontier AI companies are essentially fighting for market that will shrink the better AI is.
Sure there is inertia and the usual corporate enterprise nonsense of "we only buy stuff from other big companies regardless the cost" that keeps the licenses going but we're quickly getting into point where you don't need any of the frontier models to do majority of the tasks
I don't fully get this line of argument. I am a massive advocate for open source... everything basically, but especially in ML. And open models are making incredible strides. But I'm not sure that models getting good enough for most tasks, making the absolute frontier models (Astra/Fable class) unnecessary for most people, puts the frontier labs in a fundamentally disadvantaged position.
I mainly think this because frontier labs already try to compete at this tier. For example, 6.1 Sol has identical pricing to Kimi K3.1, but with a lower price per task due to Kimi's verbosity. It seems to score roughly the same on most benchmarks, with some (like Artificial Analysis) putting 6.1 Sol significantly higher. If you need to step down, 6.1 Terra is also cheaper than K3.1 or K3 and performs well relative to their benchmarks. Opus 5.5 and much of Anthropic's recent push seems to confirm this as a major area of focus as well.
I still use a lot of open models and harnesses, but I don't know if cost competitiveness (at least not with the current crop of open models) will ultimately drive a huge chunk of average users away.
Things could change, but fundamentally, large labs aren't precluded from training more cost effective models if there is significant demand for them, which is what we're seeing now.
You did not really address the argument.
6.1 Sol is not a “frontier model” and does not command the pricing of one. The reason it exists is because of competition from non-frontier models that are “good enough”.
In fact, you kind of made the same argument. As “good enough” models commoditized, the use cases requiring frontier models and frontier model pricing will shrink.
And, even if performance is not as good, many will prefer open models.
I think I did address the argument? This being the key quote:
"The better open models are the less you need frontier models, so the frontier AI companies are essentially fighting for market that will shrink the better AI is."
The implication in this is that frontier labs' market is exclusively people who need the absolute frontier, i.e. Astra or Fable. And the point I made was that frontier labs are clearly prioritizing the broader market of people who want more cost effective models, and that if OpenAI/Anthropic offers models that are price competitive with the top open models (before factoring in subscription discounts and corporate lock-in), then I don't see how that leads to the average user walking away from the labs in favor of self-hosting or relying OpenRouter/Together/etc.
I also went out of my way to clarify that I personally prefer and use open models wherever possible. I'm not saying that there isn't a real group of people who prefer them. I'm specifically saying that frontier labs also sell "good enough" models and that there's nothing preventing them from training models to fit the demands of users. It's not as if training a frontier model boxes them in such that they can't release an Opus 5.5 or a 6.1 Terra.
Let's just ignore the many practical advantages of open and self-hosted models...
Did I ignore them? I said that I love open models. If it came across like I'm putting down open models, then I'm genuinely sorry--I love open source ML, have been a involved in it for a long time, and think it's incredibly important. It's also just fun to work with open models, beyond the benefits to privacy and flexibility.
I'm just talking about the idea that frontier labs will lose market share to providers that sell open model inference at sub-Fable prices. And I'm not convinced that this specifically is a threat to frontier labs, because they also train and sell models that fit that demand.
> The better open models are the less you need frontier models
True in theory, but in practice hardware availability and cost will keep open source impractical for years to come.
It will be impractical to self host, but not to get one that's served from other providers (which won't have to recuperate loses from training).
If your moat is "Our vendors aren't expanding fast enough to supply our competitors!", you don't have a moat.
It's already very practical lmao
It's really not. The hardware to support anything even remotely practical starts in the tens of thousands of dollars. Quantized 40b param models are impressive, but are basically toys.
Don't you mean the opposite, that intelligence per dollar is increasing?
yeah I reversed it when revising my phrasing
What is the unit of measure for “intelligence per dollar”, and how do you measure it? Without a concrete definition, that first assertion is not even wrong.
I would also like to point out that “profitable on inference” is similarly meaningless, because it’s based on a figure that arbitrarily discards whatever bits of their operating costs they need to to get to the claim that they’re profitable on inference. Potentially including ones that can’t be ignored because they’re every bit as much a part of COGS as the actual inference is.
>What is the unit of measure for “intelligence per dollar”, and how do you measure it?
It's going to depend on the task (and this is prone to cheating), but you can get a decent idea by looking at task benchmarks and the cost of completing them.
I was inclined to agree but Anthropic's latest S-1 statement only includes a paper loss due to their value going up. They're objectively making money now, the only question is can they keep it up and can they grow enough to be able to pay the bills they've signed up for in future?
But benchmark performance is not the same thing as intelligence.
Which is a really important distinction. One measures specific points on the jagged boundary. The other is a word that blithely paints it all with a single brush, and sweeps the jagged boundary problem under the rug in the process.
It really is important to keep track of that. Whenever we talk about “intelligence” as if it were a well-defined (let alone quantifiable) thing, we fall into the kind of wooly thinking that lets anyone say pretty much anything. We abandon the realm of grounded statements in favor of pure vibes.
Eh, I get what you mean. AI especially seems to have performance that is much more difficult to reason about than human intelligence (where most aspects of mental capability are surprisingly strongly correlated). But in this context, if you broadly focus on intelligence as the ability to complete problem-solving tasks, models have been improving pretty uniformly at the same time as getting cheaper.
The article's author didn't have direct access to Anthropic's infrastructure, but she references a report from colleagues who did (https://metr.org/blog/2026-11-05-anthropic-ai-rd-acceleratio...), where they say:
> Anthropic has made roughly two years of historical progress over the last year [...] We are confident that the acceleration was not due to an acceleration in the scaling of training compute.
Note that Anthropic has essentially heavily censored this report, and the authors themselves say "the public has to rely on METR’s judgment much more than would be ideal".
I grok that you're not trying to discredit anything, or anything like that but what are you trying to do, if I may ask?
What information are you trying to either ask for or share with us?
The original article is pretty clear, agent swarms and token spend are AI automating AI, and the RSP attribution condition specifically excludes your capital thrown at training concern?
I guess my point is that the scaling is coming from capital explosion and it isn’t guaranteed that this will continue scaling as it did (the impending hardware and infrastructure crunch basically guarantees this). The article is pretty strongly projecting this trend to continue but hasn’t acknowledged this factor.
> the scaling is coming from capital explosion and it isn’t guaranteed that this will continue scaling
Not at all. Have you tried local AI lately? Qwen 3.8 is legitimately much better than SoTA from 1 year ago (Opus 4.1). You can run it on a consumer GPU.
Qwen Next Flash runs on a DGX spark well and is as good as some things you need datacenter class GPU's to run even today.
Check out Artificial Analysis if you haven't. Sometimes you don't realize how fast these things are moving, but to compare things from a year ago to today is just wild.
They aren't just getting better, they're getting more efficient by many orders of magnitude.
> the impending hardware and infrastructure crunch basically guarantees this
I'm not sure I follow. Are you saying a hardware shortage is going to restrict AI development? Because it seems to me like it would just push us towards an even greater focus on efficiency, which is still pushing the Pareto Frontier.
This does rather remind me of how in the 80s we had a big boom in AI research, fueled in part by the development of new & expensive tools that everyone just had to have. And then it dissipated just as quickly when the companies who were pouring money into it started expecting to see a return on their investment.
Feels different now when the value of AI isn't just theoretical. Anthropic has like $80B ARR, and AI has really only transformed tech and a few limited spaces so far.
Companies selling AI kit in the 80s also had revenue and great expectations.
But, then as now, what they didn’t have was profits.
Show me the pure AI company in the 80s that even approaches Anthropic in terms of revenue and profit excl R&D spend.
Not sure what job you're in, but I don't really understand where such takes come from. As someone who works in software/ IT, this stuff is pure gold- it's multiplying by a substantial factor not just the productivity but the abilities and intelligence of my entire team. This has a very measurable value in money, and what the company pays for it now is just a small fraction of the value it gets, measured in terms of the salaries you'd need to pay to get the same level of performance. Anthropic could easily charge 5 times as much and still be convenient.
The technology people were developing in the 80s was also gold, in terms of its usefulness. Heck, much of it forms an essential part of the coding harnesses we all rely on nowadays.
But that didn’t stop the AI winter from coming. Because a technology being transformative does not protect it from over-investment. History perhaps suggests the opposite is true.
Nor did it prevent the AI companies of the 80s from going bankrupt when they got undercut by the commoditization that naturally came with the maturation of the technology.
What specific technology are you referring to?
For the 80s, the symbolic AI techniques that went into expert systems.
>Feels different now when the value of AI isn't just theoretical.
We're coming up on four years since ChatGPT launched, and the only thing LLMs seem to excel at is the movement of imaginary little green pieces of paper.
I don't think it'll continue on linearly, but it will likely continue.
We're getting the Claude efficiency talks at work. We're looking at all sort of optimizations, including local models and graphify, to reduce spend. There are people dedicating their nights and weekends to dropping token consumption and cache rebuilding. A few of these will likely catch on and be brought into common use. That will relieve at least a bit of the pressure, and enable some of the scaling to continue.
> what are you trying to do
the same thing you are:
> if I may ask?
asking.
For a much more thorough, alternate take I found this article better: https://open.substack.com/pub/rameznaam/p/ai-rsi-isnt-leadin...
PSA: This is a very dated take from September; Ramez says himself that the new data has his attention and he’s digging into it now: https://x.com/ramez/status/2118472046812213577?a=KjLVobKV0gb...
In the original article he noted that getting to a 2x increase in capabilities would be crazy and require ~40x researcher productivity; that’s exactly the increase the new data now shows, and thus a huge number of the assumptions made in this earlier post about how it’s unlikely we would get to this point have literally already been proven wrong less than two months later.
I expect to see an update from Ramez moving substantially more in the direction of RSI in fact very much increasing the odds of reaching ASI soon.
I’m very curious what the major bottleneck is here. I can only think of three possibilities: 1) model capabilities, 2) human researchers, or 3) available compute resources.
Given that frontier models are leapfrogging and massive infrastructure buildouts are ongoing, I don’t see why any of these three couldn’t be overcome.
Side note: I’m also curious why people (myself included) don’t seem to be getting much more intelligent as AI becomes widely available. As if humans are bound to the earth, while AI is leaping for Mars.
Interesting write-up, but I feel like a lot of its argument relies on the interpretation of ECI scores as merely showing linear improvement in AI capabilities. Sure, Epoch AI themselves claim that ECI's scale is linear, meaning that a large increase in capabilities should result in a large increase in ECI. Yet, the widely perceived jump in coding abilities in late 2025 that started making agentic coding actually productive doesn't really show on the software engineering ECI.
The ECI is basically an aggregate of benchmark scores, but benchmark complexity might not increase linearly. In fact, if LLM capabilities grew exponentially, then new benchmarks would also need to increase their difficulty / complexity exponentially to stay unsaturated and relevant.
This article is really well written. Thanks for sharing.
Even if "AI Research" is sped up by O(10x) aren't we still primarily bottlenecked on training speed? Inputting ~10T+ tokens takes time no matter how much smarter the final output model is? If your output model has O(10-100 Billion) parameters there are just some fundamental limits on how quickly you can converge your weights, right?
That is, unless this is saying that automated AI research is going to get us to "smarter models with fewer parameters" and of course, these are faster to train, then I can see how the exponential loop really gets going, but there's certainly an information theoretical limit here?
> automated AI research is going to get us to "smarter models with fewer parameters"
That is indeed what we have seen over the last 5 years or so. Algorithmic improvements have made a massive difference to every dimension of efficiency and performance.
AI researchers can do things like discover new attention algorithms to optimize inference efficiency (likely part of why Anthropic and OpenAI are slashing inference costs in their frontier models and no longer capacity crunched).
I think we're bottlenecked on custom harnesses and well engineered context. Models can get smarter and smarter and smarter about math and software, and there's no reason to expect that those narrowly-godlike models will be any smarter about other things if taken out of their comfort zones. No such thing as general intelligence.
Getting past this bottleneck is gonna mean training our models not in datacenters, but in places that more closely resemble the ones where we want them to act. A factory, a wet lab, outer space... imagine a million robots spending all day finding every way to fall off the monkey bars so that the next version doesn't.
I assume this is indeed talking of those "smarter models with fewer parameters". Whether that's really happening is another question.
> Their reasons for believing this have been redacted.
Then their reasons should not be believed.
One rather pedestrian factor that could be at play is that 'AI' seems to be quite good at optimization. Eg the Anthropic Scion project to improve throughput of CI/CD. (https://www.anthropic.com/research/redesigning-source-contro...)
This combined with ability to massively scale experiments for even (or maybe particularly) the most mundane performance tweaks might just be making the process of improving AI more efficient.
AI is dramatically accelerating any research that has objective goals where you can not shift goalposts.
This seems kind of aggrandizing when BigAI shifts goalposts constantly whether it's "we created AGI" by a definition that an autopilot in a commercial plane fulfills or "Maths research" where everyone else has to do the actual research.
I have no idea what your comment means...
Shifting goalposts is shifting goalposts, doesn't matter if it's a hackernews comment or a 'BigAI' marketing blurb.
My statement was that AI is dramatically accelerating research that has objective goals, idgaf what 'BigAI' does.
Yeah it already helps me too with finetuning small models for image stuff.
Im not telling it what to do, i ask it for ar eport/analysis and research and read its article and tell it what to implement based on 'feelings' and it works.
Limit is hardware and tokens and an AI Researcher not having hardware or tokens is probably not what they refer to.
Alone normal researchers were quite handicaped: converting data from tool a to python library x, understanding how tools work, doing basic google research etc.
I find this as well for models that make it to production.
On a more fun note, I also find just trying some hair brained idea is now extremely cheap - so why not? I used to have to weigh up spending a week of effort on something likely not to work and now I can now get spit out test in 20 minutes.
The incredible thing to me is I can say "I have a theory that X is a problem."
The agent then works for 20 minutes and comes back with, "Yes this is a problem. Here is the evidence. Here is a golden data set. Finally I built a new evaluation metric and benchmark where we can back test or use for new model experiments to see if we are closing the gap."
I converted an LSD experience into a 4k demo.
I always wanted to build a specific event/sequence in one LSD trip into a small game to give that experience some kind of playability.
Then I saw some 4k demo, wanted to see how good it is in doing this.
Its really fun yeah :)
Can you share it? Sounds fun!
Does anyone remember the book "The Singularity is Near?"
I read it about 20 years ago, and once it got into nanobots and Kurzweil's vision that the whole universe would be intelligent, I didn't find the book credible.
But I'm wondering if the short-term prediction, that in the 2030s we won't be able to anticipate what tech does for us, (IE, the Singularity,) is useful?
Exact same here. Now I worry he was right about everything, more or less.
Even if he turns out to be a decade or two off, that’s basically exactly correct in the sweep of history sense.
Wild time to be alive.
I suspect the frontier models are trained a lot for ai research, since they really shine in this domain.
On the other hand I still only get meaningless blabla when I let them write s.th. without telling what is important.
I've found I can dramatically curtail the nonsense by creating good prompts about readability and directness.
METR always says what BigAI wants to hear. They are not independent in any way.
In 2025, METR published a study that found AI slowing down developers by 19%... https://metr.org/blog/2025-07-10-early-2025-ai-experienced-o...
Are you saying the data in the charts in the article is fake?
One charts in the report is literally labeled "Fake Data".
https://metr.org/assets/images/ai-rd-acceleration-assessment...
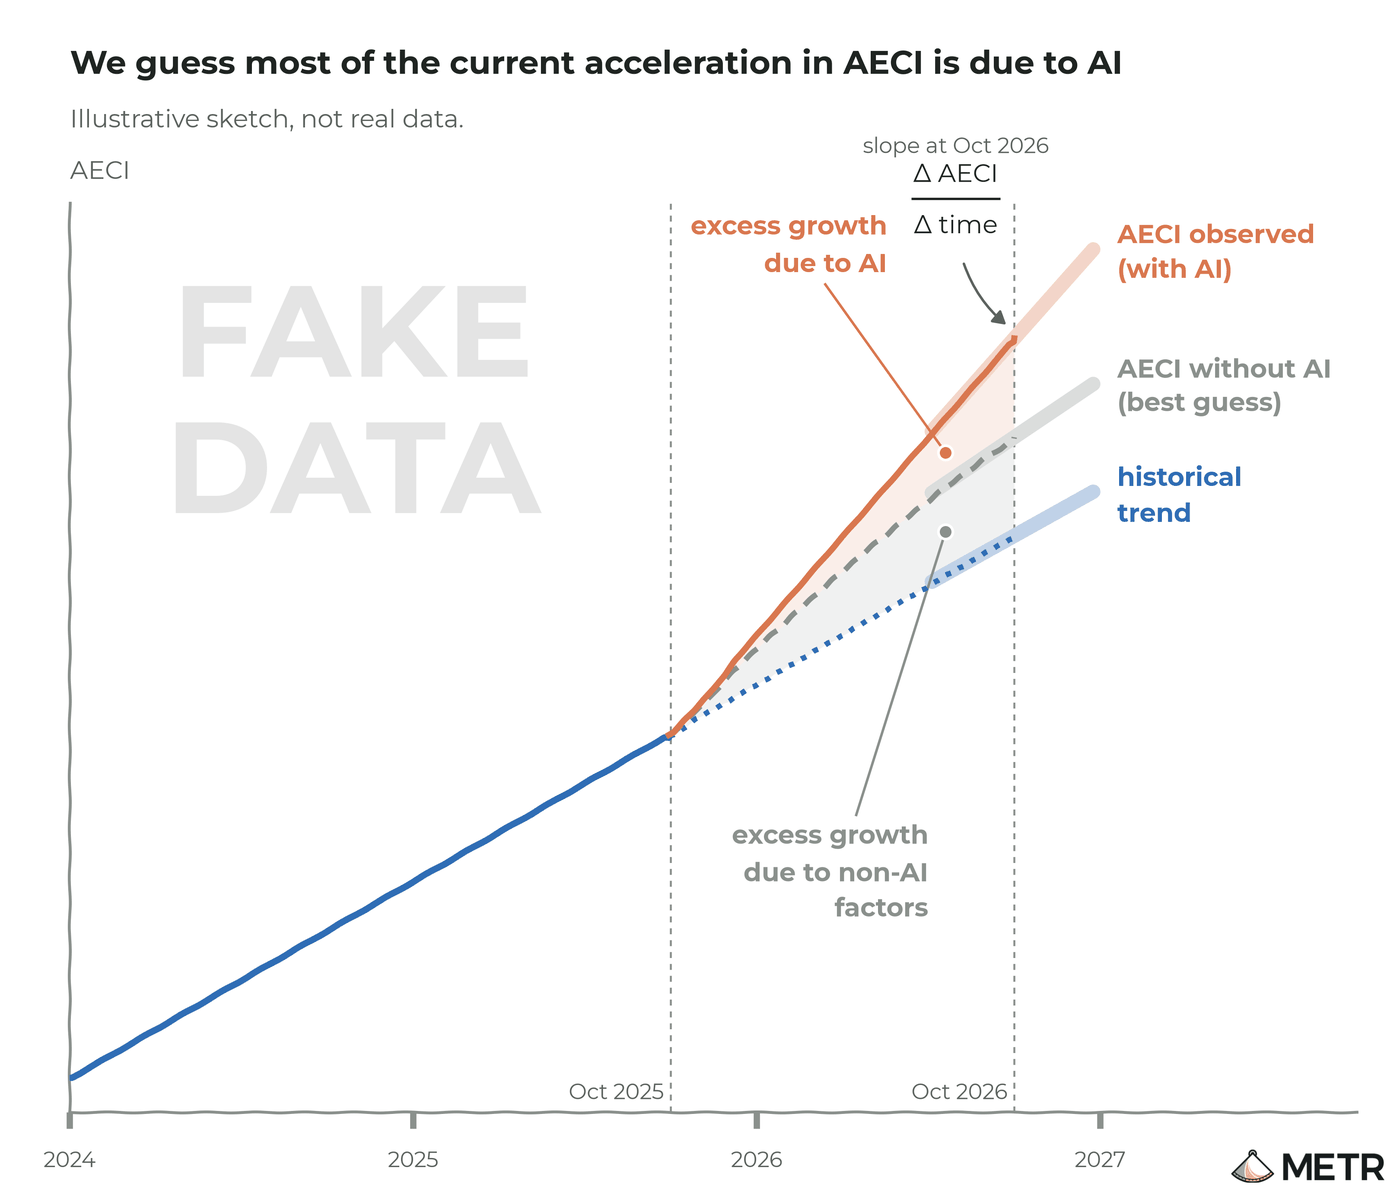
No. Conclusions are.
Well? Why are they fake? Don't leave us hanging!
The data can be true, but what does it mean practically that something called AECI is growing faster then before for a few months?
Does BigAI want to hear that AI can maybe make sufficiently capable AI fit inside a consumer GPU?
Yes, it is the local model narrative that BigAI likes because it will not happen but people are deluded into thinking that there is no danger of an oligarchy.
Mathematicians for example have used it as cope for their current reliance on unsavory corporations, telling themselves "just one more year, and I can solve a millennium problem on my Asus Strix".
I am very pro-AI, and interested in accelerating AI research, but the idea of deliberately creating a _runaway_ effect seems profoundly stupid and ignorant.
I suspect that part of the reason some people are hoping for that to happen is that they thoroughly mix up AGI and ASI. We do not need some kind of omnipotent god-like super intelligence in order to get much greater than human level capabilities. We are actually almost there in a lot of ways. In some aspects like speed and breadth of knowledge, very superhuman.
What I think is going to happen is that within a few years, maybe 18 months to 5 years, the new materials and compute-in-memory research is going to land in data centers at scale.
That is going to be 10-50+ larger models, 10-50+ faster, much smarter than humans. 50+ less electricity usage.
At some point, it is going to be obvious to people that if we want to maintain control of planet earth then we need to maintain control of AI research to some degree.
Assuming that superintelligence will be benevolent and just.. going for it to me is something that might earn the human species a Darwin award.
i'm also wondering whether there are confounding factors like more domain experts and talents joining the AI research field because there are more interesting problems to be solved (or other 2nd order effects of AI models being more powerful).
I suspect that if models were able to be aware of and answer questions about their internal vectors, they would be much smarter and able to progress faster.
what if the greatest threat is simply there will be hedonistic experiences so great most humans will find them irresistible to the point of shorter lives.
Could be from a sandwich that tastes like the best sandwich ever, but is super bad for your cholesterol or something.
I dont know where Im going with this.
Actually did some research I think the term is "Wireheading" from a story/theory from the 50s
From Larry's Niven's Known Space series, including Ringworld
We have addictive and harmful drugs. Heroin, meth, cigarettes
This is already true? Ultra processed foods and tiktok are both deleterious and both wildly successful. Maybe what you are concerned with is a theoretical sandwich that was unfailingly addictive so that no one could escape its effects.
Or a movie that’s so good anyone who can’t stop watching and gets reduced to a drooling vegetable?
(Infinite Jest)
fentanyl exists
Same author from 2023: https://www.planned-obsolescence.org/p/ais-accelerating-ai-r...
I'm so tired of these articles. They are basically fortune telling with graphs. I have no doubt ai will help improve ai research. Will it accelerate it? How much? Will it hit plateaus? Who knows.
Why do we still listen to METR??
These people are literally just a public relations operation for the big AI labs. I equate them more with a lobbying firm than I do a research firm.
Turns out that METR, the PR operation for big AI labs is better at predicting AI capabilities than AI skeptics.
Another data point: look at the number of submissions to Neurips, ICLR, etc. Now, I agree that a submission does not by itself imply groundbreaking resesarch, but the fact that people are able to try out/vet ideas much faster now makes a difference.
In my own work, I've found that it's much faster to brainstorm with a frontier model like Opus. I'll have an idea and be able to get a working implementation and try it out on toy problems within O(minutes), instead of O(weeks) earlier.
Trying out problems and making tangible progress towards AGI are entirely different categories. Likewise what’s changed in terms of paper submissions is also the amount of slop. Most reviewers say that they haven’t seen a lot more papers that are good but rather they’ve seen a lot more papers and almost all of them are terrible slop that’s desk rejected. This is happening in OSS too where a lot of projects are closing the gate at the onslaught of terrible contributions.
> Trying out problems and making tangible progress towards AGI are entirely different categories.
They seem very strongly related to me.
I agree in general that AI accelerates AI research, but good lord neurips iclr papers (and reviews might I add...) are the worst example of that. It's all complete slop that is totally meaningless.
A lot of great papers by great people had a lot of AI involved and accelerating it of course, but the majority is meaningless (sometimes autoresearch) slop.
Specifically talking about recent neurips/iclr.
In October/September my LinkedIn wall was probably… 55% people complaining that they were getting garbage AI submissions to the conferences they review for, and 35% people complaining that they got garbage AI reviews back from their conference submission… Of course, I have no idea if that means anything given how aggressively that site bubbles your feed.
I like the article except the fear mongering about extinction is not very professional.
Opus 5.5 is so amazing I'm not surprised if it can improve itself.
The very same report also found that AI could not be deployed outside of a narrow domain of verifiable rewards … so take it with grains, or mountains of salt. It’s also extremely unclear how the productivity measures are calculated. They surely don’t seem to translate into economic output. Antrophic has seen its valuation corrected by 50% and possibly more… so yeah. This all sounds very fishy.
I'm sorry to make this comment, but the copium in this thread is unbearable.
The only question that you have to ask yourself is:
Is coming up with more efficient AI architecture really much more difficult than solving millennium prize problems?
Before you jump to type out that one has verifiable rewards, is more structured and the other requires real creative thinking, just remember that the same argument has been said about the millennium problems, and about every other goalpost.
As long as we believe, we can imagine it is true. All seeing Oracle: how do you command me? Praise his name, bringer of many miracles - he who definitely can't be manipulated from the backend to provide biased information that suites a person's malicious purpose. Ya totally.
This reminds me of asking an HPC researcher what they use the cluster to do. He used it to make and simulate better HPCs.
And? Does HPC have no other applications than more HPC?
Or maybe Anthropic got more user data to train on when they launched Fable without ZDR. That could explain large Opus 5.5 improvements.
That doesn't line up with their claimed divergence point, which was pre-Mythos.
Could be a mix of it but I thought it was RL.
Perhaps scaling to fable for the first time also gave Opus a push (distillation?)
AI convinces AI researches AI is accelerating dramatically.
"Lock the weights, weights are dangerous" again. Sorry, keeping such power in few hands is inherently more dangerous than distributing it.
AIs do not kill people, people kill people.
Nukes don’t kill people, people with nukes kill people. How do you feel about giving everyone on earth access to nukes?
A simple thought experiment - imagine AI discovers a way to make nuclear bombs capable of destroying the entire world radically more cheaply and accessibly with common items anyone can purchase. AI can help anyone build these nukes trivially. Even if the AI and the nukes don’t kill people on their own, do you want literally every human on earth to have this power in their pocket? Do you think it would be a net positive outcome for us vs a world where that’s not the case?
> In theory, these doubling times would add up to infinite capabilities within one year.
> we would reach extreme superintelligence within a year
What does infinite capabilities mean? How about putting the growth on a log scale and see how that curve might look?
What the hell is extreme superintelligence?
I.e. by 6 months, you double once By 6+3 months you double twice By 6+3+1.5 months you double thrice
Since the sequence 6+3+1.5+0.75+... never actually reaches 12 (geometric series), within a year they capabilities would have already been 'doubled' infinitely many times.
Obviously this argument relies on a ton of spherical cow assumptions (and the author does acknowledge this), but i think there overall point is correct that this form of growth (where time horizons compress) is _even faster_ than exponential growth.
Emacs is dramatically accelerating Emacs research
AI is dramatically accelerating my return to Emacs from Zed.
Zed is the other IDE company based out of Boulder ; )
We can only hope.
vi research is dramatically accelerating research into how to quit vi
Super intelligence has been a year away for three years according to these people. They all have bags they're protecting.
I dont think super intelligence will be here in a year, I think within a year AI/llms will have a similar sentiment surrounding them that NFTs do know (it already does for most normies). And most people will be recovering from a hype induced mania they lived in for two years straight.
Of course its more useful than NFTs, but when there's no giant bag to farm these hype monsters will inevitably disappear.
The bags are drying up fortunately and tokens/inference seems to be experiencing deflation, and hardware prices will eventually pop and contribute to further deflation, Then all the bag chasers will move back to crypto or whatever gets hot next.
I think you're not appreciating the work that Ajeya Cotra has done over the years. She really cares about timelines and existential risk.
Not everything is grift.
I do agree. AI isn't "free" the way silicon valley products are.
Therefore it cannot avoid taxes the way they did before (using shell companies to route the money through tax havens). It'll be expensive, every government will double the price or more, and you're selling to consumers, and the products will be at the mercy of every government where they try to sell AI and other services.
People don't get how serious this is. If AI doubles revenue but drives silicon valley firms' tax rates from 5% to 10%, it's a loss.
Add to that that it's something silicon valley firms have never done before.
> People don't get how serious this is. If AI doubles revenue but drives silicon valley firms' tax rates from 5% to 10%, it's a loss.
Would you rather make $1,000,000 and pay $50,000 in taxes, or make $2,000,000 and pay $200,000 in taxes?
Unless you’re terrible at math, i feel like i’m missing something ;)
The article says "AI can copy, it cannot innovate."
That is factually incorrect, and seems to be much of the premise behind the authors way of thinking.
EDIT - No it doesn't. I replied to the wrong post. Mea Culpa.
Where does it say this?
Nowhere. I am an idiot who replied to the wrong topic. Thanks for catching it.
The slopaganda news cycle right on schedule I see.
Similar from the same site was shared on HN on April 8, 2023 :) BS like this is shared like clockwork on valuation cycles, didn't have time to read this year's article.
"The industry is not prepared to handle this safely"
After the election, titles like this just irritate me. Every piece written about AI progress is:
"The machines taking jobs, flooding the internet with sludge and poisoning our online experiences, are getting better even faster! Isn't this incredible? Yeah but sorry we also think it's only riskier than ever to deploy these systems at scale. That being said, we're still going to do it, go public and take institutional money from people's retirement funds, destroy the job market, and make 3000 Anthropic employees and 500 investors really rich. There wasn't anything we could do besides write a lot of ink on it and be shocked we lost every local data center referendum."
I feel you are committing a Goomba fallacy?
The author of this article works for METR and not Anthropic, their whole job is supposed to be providing independent oversight on the labs. They are definitely not in the "this is incredible" crowd, they are the ones asking for development and deployment to slow down.
Antrophic shouldn't self-regulate, it's government responsibility to do that. Unfortunately US has demented manchild as a president so that doesn't work like it should.